Minecraft name: artefox
What’s a thing you have made which demonstrates sufficient engineering knowledge?:
I made a pipelined CPU, some specs are:
-
4-stage pipeline (fetch, decode, execute, writeback)
-
8-bit architecture with 2 byte instructions
-
Handles all hazards
-
0.36 Hz / 28-tick clock @ 10 rtps
-
4,096 bytes of program memory (2,048 instructions)
-
128 (2x64) bytes of instruction cache
-
64 bytes of memory
-
4 bytes reserved for memory-mapped I/O ports
-
7 general-purpose registers and a zero register
-
16 deep, 11-bit general hardware stack used for both push/pop and call/return functions (Call and data stack)
-
Full 11-bit jumps/branches covering the entire program space
-
A storage format to convert machine code into signal strength barrels (for the program ROM): ROM Protocol
Along with that, I wrote an assembler for my ISA, and then a schematic generator which turns machine code into barrels for the ROM.
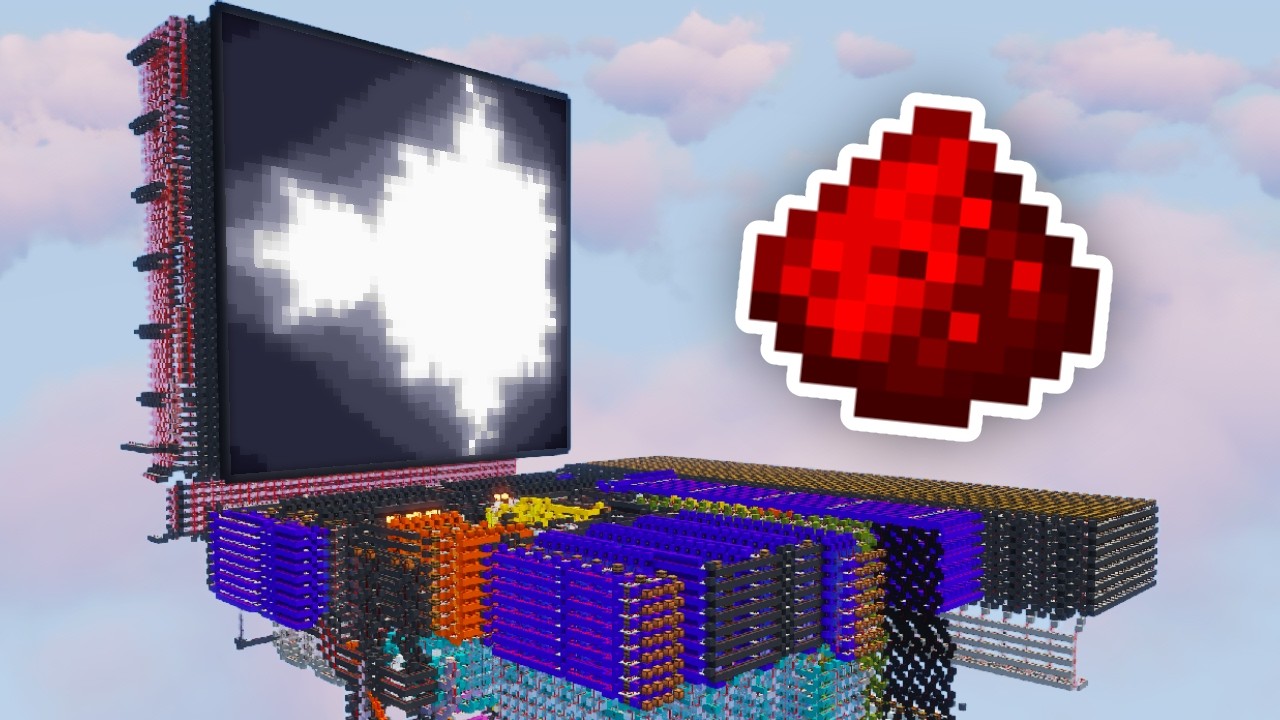
I also wrote a few ambitious programs for the CPU. First I wrote the Mandelbrot Set, which I made for a 45x45 pixel display with 16 colours. The display uses retextured redstone dots to display coloured pixels. The program does 24 iterations for each pixel and uses signed 8.8 fixed point values for calculations, so it includes a signed 16-bit software multiplication algorithm. Then, I wrote a graphing calculator, which graphs polynomials up to degree 5, ranging from -2 to 2. It then outputs to a 128x128 monochrome display. The algorithm also connects the dots to make the graphs continuous. Lastly, I wanted to make a fully-accurate Minesweeper program, with accurate textures, win/lose routines, and HUD elements. The board is 10x10 cells, with 15 randomly-generated mines. This also uses retextured redstone to display textures and the face display. Also, it uses redstone lamps to display the flag counter. Overall, this project took me a little over 2 years from start to finish. (July 2024 - August 2026)
What engineering work went into designing this device?:
First, I started brainstorming the pipelined architecture. I knew I wanted to run large programs so I definitely needed a large ROM with an instruction cache. A four-stage pipeline seemed the most intuitive for me, so I went with that. Before placing a single block, I was drawing out diagrams of the dataloop, and instructions as they went through the pipeline to handle hazards. The first hazard I encountered was having to read a register during decode, while the value may still be in the last instruction’s execute stage. To solve this, I made a circuit to detect if the last destination address matches the current read address, and if so, read from the ALU/memory output instead of the register. (Forwarding) Though, this introduces a new issue: When reading register zero right after writing to it, you’d expect zero (since it’s a zero register), but this way you’d get the forwarded value. So I implemented another circuit to detect if it’s reading zero to cancel the forwarding process. Another issue I had to deal with due to pipelining, and this one took the longest to figure out by far was branching. By the time the instruction knows whether to branch or not, the three next instructions would be already loaded. And if it turns out that the branch is taken, it would have to effectively cancel those next instructions. So to solve this, I looked through my control lines and made a circuit that can cancel any writes. (Memory store, registers, stack, PC, etc.) Then after that it loads the new instructions just fine. Also, there was almost another hazard I ran into, which is reading a register value two instructions after writing to it, which means the 2nd last instruction would be in the writeback stage while it is currently in the decode stage. So I realized that when writing back, I would have to send the write back pulse earlier than the next clock cycle, basically using the last cycle plus a bit of delay, so that it can read the value in time. This saved having to use another forwarder or something. I also ran into a weird dilemma: When returning from a subroutine, it should pop the address it came from (+1) and then jump to that, and the popping here happens during the execute stage. And during the call instruction, it was pushing the address+1 during the decode stage. So this setup broke in a specific situation where a branch takes place right before the call instruction. That means the call instruction is loaded in the pipeline even though it’s wrong, and therefore the stack’s write signal should be blocked. So I was like alright, let me block the stack signal during the call’s decode stage. But then what if it’s coming right after a return instruction, which is already in the execute stage, where it performs its stack operation? I needed it to somehow block the push signal but let the return’s pop signal go through and this didn’t really work well in my system where both of those signals shared the same pulse. So, eventually I found a solution which was to offset the call’s push instruction by a stage so it would happen during execute, just like every other stack operation. The only reason that it was happening during decode was because that’s when the address was address+1. So to fix that I just added a latch in the PC->Stack bus as well so it gets address+1 instead of address+2.
I really wanted to be able to write ambitious programs with the CPU, and I wanted people to try it as well, so I carefully designed the ISA to reflect that philosophy. The ISA is very intuitive to understand, and I made sure that you don’t need any knowledge on what’s happening during the pipeline when writing programs. (Like the forwarding R0 “bug”, cache loading, etc.) It’s crucial to me that these things are invisible to the programmer. I also made specific design choices like memory mapped I/O ports, and combining the call and data stacks together to make it simpler for people to use the CPU. I wanted it to be only as complicated as it needs to be. Also, it was very important to me that you can jump/branch anywhere in the program, and I made that possible by incorporating the branch conditions in the opcode so the rest of the 11-bits fit perfectly as an address covering the entire range of program memory (2,048 instructions). I also genuinely wanted to learn how everything worked, for example when borrowing the program counter design, I studied it thoroughly before using it, and I designed the entire pipelining layout, computer architecture, barrel ROM protocol, etc myself. Though this wouldn’t be possible without the help and support I got from so many ORE members.
With the program memory, I did something a little special. The barrel ROM can store 4 bytes per column, and is 16 columns long, which is exactly a block of cache (64 instructions). Though my CPU instructions are 2-bytes, so I made it so that the ROM can output two serial streams of signal-strength hex values simultaneously, and one gets decoded into the “high” half of the instruction cache, and the other in the “low” half representing the lower part of the instructions. It’s kinda hard to explain what I did but I’ll try my best. When reading a block of ROM, a wire runs through the entire length of the block as the rows of barrels beside the signal flow into two separate signal-strength hex buses, one being for high bytes and low bytes. And due to the nature of the ROM design, the order of the high and low bytes of the instructions alternate. For more information on my “ROM protocol”, click the link above. So, it was kinda tricky to figure out the math for this unique configuration while writing the schematic generator, but eventually I got to a solution where I just check if the row pairs are odd/even to determine which way to order the high/low bytes in memory. So when the program counter reads an instruction, the 11-bits are split into 5 upper bits determining the block in ROM, and the 6 lower bits to locate the address in cache. So I have a little circuit to detect if the loaded block of ROM matches the current block (upper 5-bits), and if they don’t, then it will automatically trigger a new cache load. And when reading a block of ROM into the cache, the process takes longer than a clock cycle. So what I did was pause the clock (stalling) for the duration of the cache load until it was done, before the wrong instructions could ever get into the pipeline. This is also an example of something I wanted to be completely invisible to the programmer.
Also, writing the programs came with their own engineering challenges, especially with Minesweeper. I wanted to make it as accurate as possible to the original. One of the biggest workarounds I had to do was allocating a byte to two cells on the board, since I chose to go for a 10x10 board, and I only had 64 bytes of memory. This way, each cell would be 4-bits and would take up 50 bytes in total, and in the program I had to test if a coordinate belongs to the high or low half of a byte every time I want to read/write to a cell. The original textures for Minesweeper are 16x16 and I wanted to make it so that one pixel of the texture is the same size as one in-game block, and I would use retextured redstone dots as pixels. But block models can only be up to 3x3x3 in vanilla, so what I did was change the transparency of the texture to a specific value, then use a resource pack shader to detect that alpha value and scale the vertices of that block to 16x16, while the actual model is a tiny square. Also, for the face at the top, I wanted it to be dynamic, which means adding 5 facial expressions, and I didn’t have that much redstone dot blockstates left to use, so I used an “illegal state” where only one side of the redstone is enabled, so it won’t retexture regular redstone. Also, Minesweeper has a flood fill algorithm when you press on a cell with zero neighbouring mines (zero-spreading). Normally you’d implement some sort of algorithm where you push neighbouring zero-cells on the stack then repeat the process one-by-one, but my stack was only 16-long, which is too little. Instead I thought of a system where it sets all neighbouring zero-cells to a “marked” state, then it’ll scan the entire screen, and repeat the process for every time it hits a “marked” cell. This method for floodfill doesn’t use any extra memory, though it is a bit slower than regular flood fill. So most workarounds sacrificed time for memory, which was basically negligible thanks to MCHPRS.
Image/s and/or video/s of the device:
 )


 does it… but all the staff have lives, too busy to accept


